
Collecting web data should not automatically mean building a crawler, maintaining proxies, or learning how to keep a browser automation script alive.
For many marketing, ecommerce, research, and operations teams, the real goal is simple: get usable public data into the workflow where decisions are made. That could mean competitor prices in a spreadsheet, public product information in a database, search-result data for SEO research, or fresh page content for an AI workflow.
What makes web data collection difficult
A page can look simple in a browser and still be difficult to collect reliably.
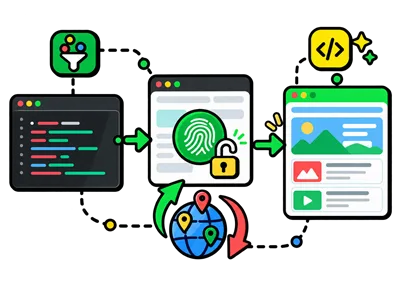
The data may load only after JavaScript runs. A site may require a browser session, show an access check, or change its page structure. At scale, teams also need to handle retries, routing, output formats, and failed requests.
Building these capabilities internally can turn a data-collection task into an engineering-maintenance task. Clawoxy is designed to handle much of that underlying work, including browser rendering, access-related handling, retries, and output delivery. Clawoxy’s Web Unblocker can return a target page as HTML, Markdown, or a screenshot, while its platform-specific Scraping API returns structured public data for supported sources.
You do not need to build a scraper from scratch
“Without coding” can mean different things.
A visual no-code tool may let a user click page elements and export a file. Clawoxy takes a different approach: it is API-based. Its official workflow requires sending a request with a URL or supported extractor parameters.
That means the first connection may need help from a developer, an API client, or an automation workflow. But once it is configured, the business team does not need to own a scraper codebase, manage proxy pools, or troubleshoot browser rendering every time a website changes.
This is often the more useful definition for teams that need repeatable public web data: not “zero setup,” but “no scraper infrastructure to operate.”
A simple process for non-technical teams
Start with one repeatable question, not a broad request like “scrape this website.”
For example:
Track the public price, availability, and review count for a list of competitor product pages once per day.
This gives the workflow a clear target:
- Choose the source. Identify the public site or platform you need to monitor.
- Define the fields. Specify exactly which information matters, such as product name, price, rating, date, or URL.
- Choose an output. Decide whether the result should go to a spreadsheet, database, dashboard, or AI workflow.
- Set up the first request. Use a technical teammate or approved integration to configure the API connection.
- Validate the first results. Check that the fields are complete, correctly formatted, and useful before relying on them.
- Make it repeatable. Run the same workflow on a schedule or trigger it when the business needs fresh data.
The value is not just getting one page successfully. It is having a workflow that can produce usable data again without requiring the team to rebuild the collection system.
Common ways teams use public web data
Ecommerce and competitor research
Ecommerce teams can collect visible product details such as prices, stock signals, ratings, review counts, and listing information. This can support pricing reviews, assortment research, and competitor monitoring.
Content and social research
Teams can organize publicly visible videos, posts, hashtags, or creator-page signals to understand content patterns and market conversations.
SEO and search monitoring
Search data can help teams review current rankings, ads, related questions, and other visible search-result features. This is useful when planning content or monitoring changes in search visibility.
AI and knowledge workflows
Clean Markdown or structured content can be easier to review and send into a knowledge base, retrieval workflow, or internal research process than raw page HTML.
What to check before collecting data
No tool removes the need for judgment.
Before collecting public web data, make sure you understand the source’s applicable terms, legal requirements, and any limits on how the data may be used. Only collect data that is appropriate for your intended workflow, and validate the output before using it in business decisions.
You should also be realistic about data quality. A successful page request does not automatically mean every field is accurate, current, or complete. Define your required fields, inspect sample outputs, and decide how your workflow should handle missing or changed data.
Start with one useful workflow
The best first project is narrow and measurable.
Choose one public source, one page type, and a small set of fields that answer a real business question. Configure the initial connection, review the output, and expand only after the workflow proves useful.
With Clawoxy, your team can focus on using web data instead of building and maintaining the infrastructure required to collect it. Explore Clawoxy to identify the product that fits your data workflow.